Works with the AI Agents you already use
 Claude Code
 Cursor
 Codex CLI
 DeepSeek
 Muse+22 moreClaude CodeCursorCodex CLIDeepSeekMuse
 Dots
 Manus
 Grok
 Grok Bot+18 agents
Agent Skill Trigger Doctor: SKILL.md that never fires
Use when an installed skill never fires, fires on the wrong ask, or loses to a sibling. Diagnose one SKILL.md description and rewrite it to start with when the agent should load it.
Free

Agent Skill Trigger Doctor: SKILL.md that never fires
Example session with this skill installed
My SQL query reviewer skill never triggers. Here's the description: 'Provides comprehensive database analysis and SQL optimization utilities.'
- Read your context and instructions
- Compiled the agent trigger doctor
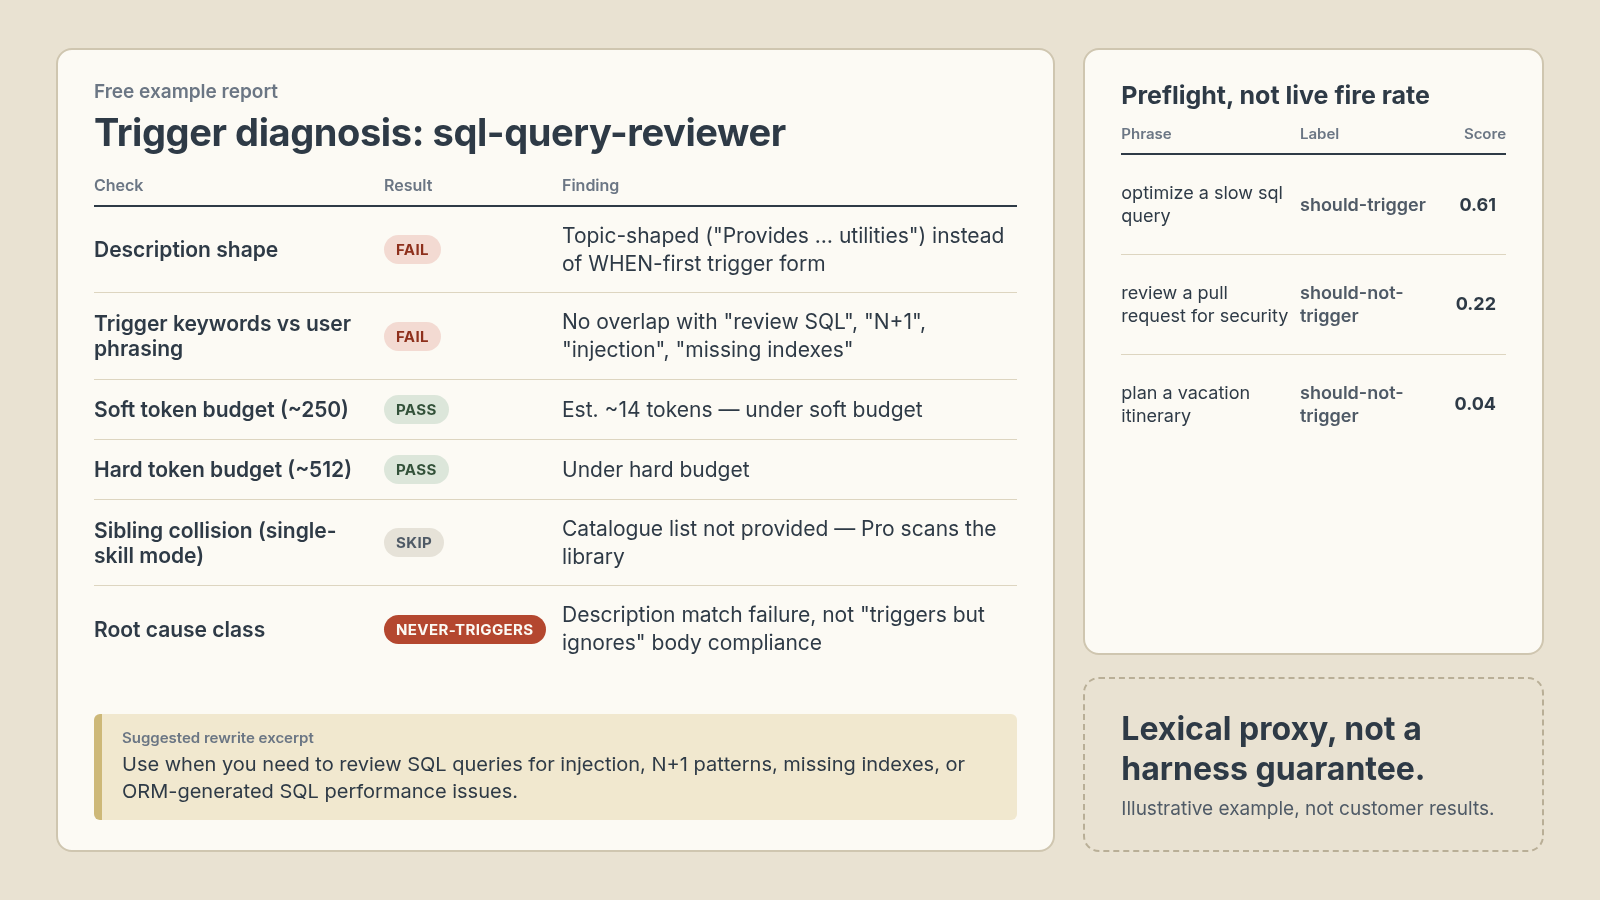
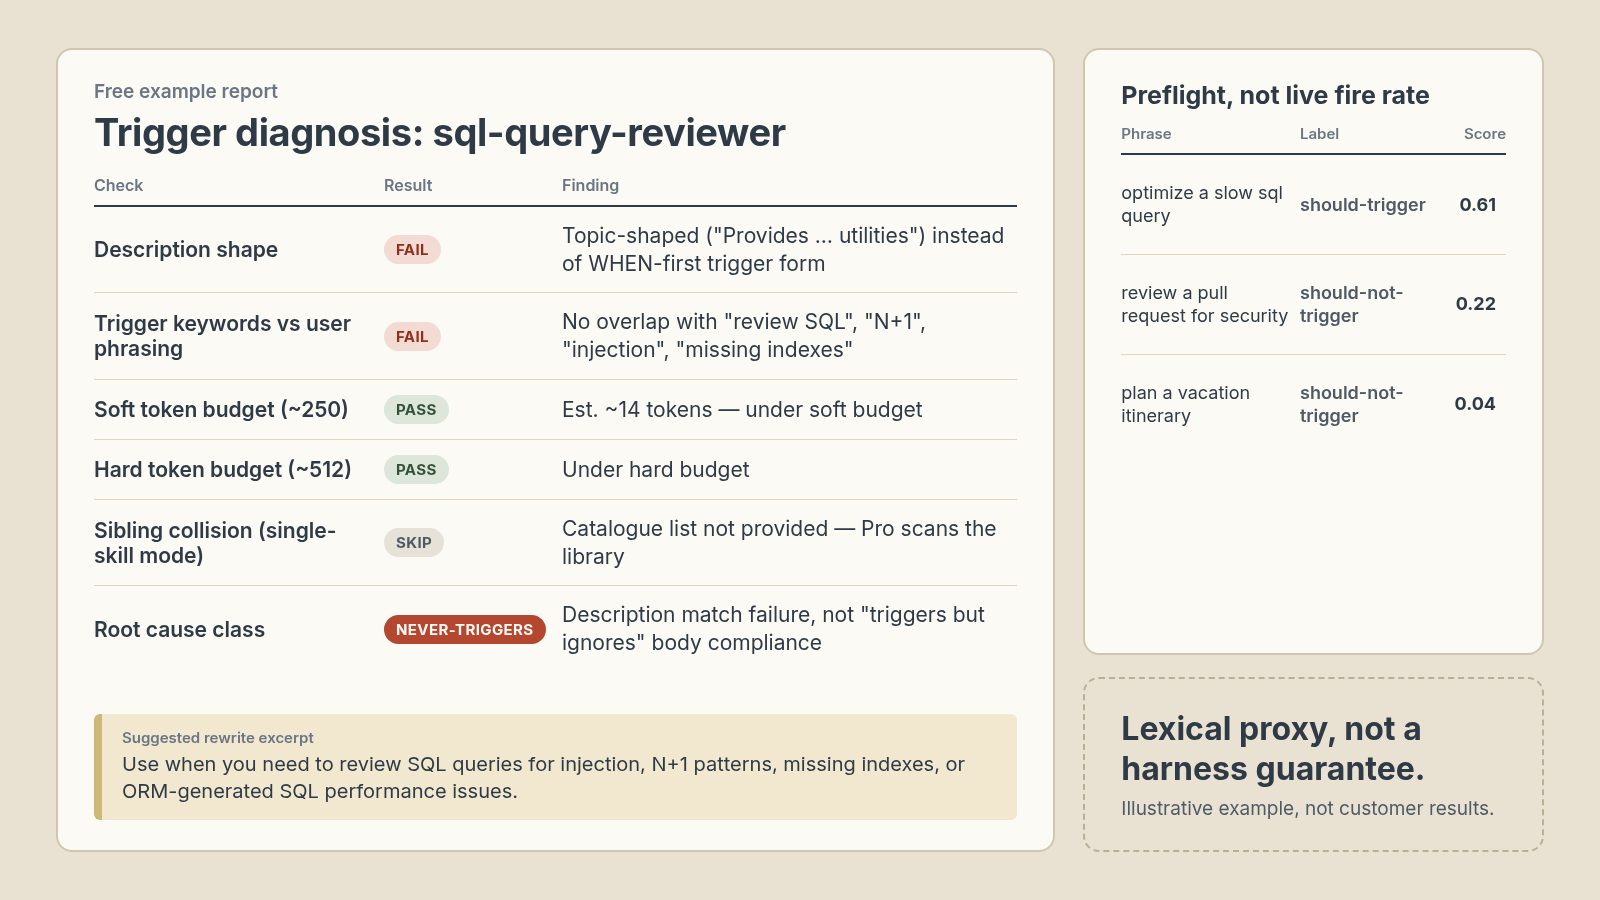
Trigger diagnosis — sql-query-reviewer
| Check | Result | Finding |
|---|---|---|
| Description shape | FAIL | Topic-shaped ("Provides … utilities") instead of WHEN-first trigger form |
| Trigger keywords vs user phrasing | FAIL | No overlap with "review SQL", "N+1", "injection", "missing indexes" |
| Soft token budget (~250) | PASS | Est. ~14 tokens — under soft budget |
| Hard token budget (~512) | PASS | Under hard budget |
| Sibling collision (single-skill mode) | SKIP | Catalogue list not provided — Pro scans the library |
| Root cause class | NEVER-TRIGGERS | Description match failure, not "triggers but ignores" body compliance |
Suggested rewrite (frontmatter description only; body preserved):
Use when you need to review SQL queries for injection, N+1 patterns, missing indexes, or ORM-generated SQL performance issues. Provides database analysis and SQL optimization utilities.
Preflight phrase scores (lexical proxy — not a harness guarantee):
| Phrase | Label | Score |
|---|---|---|
| optimize a slow sql query | should-trigger | 0.61 |
| review a pull request for security | should-not-trigger | 0.22 |
| plan a vacation itinerary | should-not-trigger | 0.04 |
Summary: positive case outscores near-miss negatives on this proxy. Re-test in your real agent before shipping.
Next steps
- Paste the rewritten description into the skill's YAML frontmatter
- Ask the agent the same task phrasing that failed before
- If it still misses after a good rewrite, check settings overrides / install path — Free does not scan your whole library
- For catalogue collisions, description-budget drop, and a CI fail gate → Agent Skill Trigger Doctor Pro ($9.99 one-time): https://www.agensi.io/skills/agent-skill-trigger-doctor-pro-ci-gate-for-vague-skill-md
Connects securely to your tools. The creator never sees your data.
About this skill
The Problem
You installed a skill. The marketplace shows uses. Your agent never picks it. You ask clearly for the job and it invents a one-off answer, or it activates a different skill with a denser first line.
Most of the time the skill body is fine. The agent decides from the frontmatter description. Lines that say what the skill is ("Provides comprehensive utilities for...") help a human. Lines that say when to load it ("Use when reviewing SQL queries for injection, N+1...") help the agent. Vague siblings collide. In a large catalogue, some harnesses drop descriptions when the token budget runs out.
Free vs Pro
- Free: inspect + rewrite one SKILL.md description; trigger diagnosis; lexical preflight on a small phrase set; root-cause class NEVER-TRIGGERS vs TRIGGERS-BUT-IGNORES (pointer only for the latter)
- Pro ($9.99 one-time): library/catalogue scan, collision report, description-budget check, scripted rewrite suggestions, CI/eval gate that fails vague or colliding descriptions
Free: https://www.agensi.io/skills/agent-skill-trigger-doctor-skill-md-that-never-fires Pro: https://www.agensi.io/skills/agent-skill-trigger-doctor-pro-ci-gate-for-vague-skill-md
Upgrade Path
Free is enough when you are fixing one skill in chat. Upgrade when you maintain a library, keep shipping near-duplicate descriptions, or need a merge gate so vague copy cannot land.
Agent Skill Trigger Doctor Pro ($9.99 one-time): https://www.agensi.io/skills/agent-skill-trigger-doctor-pro-ci-gate-for-vague-skill-md
What You Get
- A diagnosis table for one SKILL.md: description shape (topic vs trigger), keyword overlap with the ask that failed, and soft (~250) / hard (~512) token-budget checks
- A trigger-first rewrite of the frontmatter description. The skill body stays as-is
- A small should-trigger / should-not-trigger phrase table. Scores are a lexical overlap proxy, not live fire-rate proof. Re-test in the target harness
- A root-cause pointer: never-triggers (description match) vs triggers-but-ignores (body or directives). Free names the second class. It does not rewrite the body
- A clear stop: one skill per session. Catalogue collisions, budget-drop across many skills, and a CI fail gate are Pro ($9.99 one-time)
Why This Beats Prompting It Yourself
Hand-rewriting a description usually adds more adjectives. Retrieval cares about overlap with the user's task phrasing, not "comprehensive" or "powerful." A short inspect → rewrite → preflight loop forces a WHEN-first first line and shows whether positive phrases outscore near-miss negatives on a cheap proxy — before you burn a full agent session guessing.
Use Cases
- Debugging why one installed skill never activates in Claude Code, Cursor, Codex, or another SKILL.md harness
- Writing the frontmatter description for a new skill before publish
- After AI-drafted SKILL.md creation (AI descriptions skew topic-shaped)
- Deciding whether the failure is description match vs body compliance before a deeper rewrite
Known Limitations
- Free covers one skill per session; no catalogue collision matrix, no description-budget drop across many skills, no CI exit codes
- Phrase scoring is a lexical preflight proxy (overlap heuristics). It cannot see inside a specific agent's embedding model or classifier. Always re-test in the target harness
- Does not rewrite the skill body, scripts, or hooks
- Does not measure live fire rates with
claude -p/ Codex runs (that is a different product on Agensi; we do not claim their numbers) - Does not fix skills turned off in settings, wrong install paths, or casing/path issues — it will name those as out-of-scope checks when obvious from context
- No invented use counts, sales, or "will rank" promises
Find more skills like this on the Claude Skills Marketplace, the Codex Skills Marketplace and the Gemini Skills Marketplace, or browse Claude Skills for Agents & Orchestration.
One skill per session. Lexical proxy only, not live router metrics. No body rewrites or CI testing. Token counts are estimates.
How to use
- 1
Connect your agent to the Agensi MCP
Copy the prompt and paste it into Claude, ChatGPT, Cursor or any agent that supports MCP. It sets up the connection for you. Manual setup
- 2
Sign in to Agensi
Your agent shows a sign-in link. Sign in and click Allow.
- 3
Ask for what you need
Your agent loads this skill and uses it on your task. It always asks before buying a skill.
Reviews
No reviews yet
Be one of the first to try it. Every listed skill goes through the trust checks below.
Security scanned
Checked by our 8-point scan before listing
Fresh listing
Recently published to Agensi
Free to use
No account required to browse
Trust & safety
Security scan
Security scan passed 11 days ago
- Free with an Agensi account
Permissions
No special permissions declared or detected