Works with the AI Agents you already use
 Claude Code
 Cursor
 Codex CLI
 DeepSeek
 Muse+22 moreClaude CodeCursorCodex CLIDeepSeekMuse
 Dots
 Manus
 Grok
 Grok Bot+18 agents
Context Budget Engineer
Cut agent context without losing quality: per-section budgets, techniques and a measured before/after.
$15

Context Budget Engineer
Example session with this skill installed
Our agent is slow and expensive and sometimes ignores its instructions. Here is the assembled context for a typical request with token counts per section. Fix the budget.
- Read your context and instructions
- Compiled the context budget engineer
Worked example — illustrative data.
Context budget: support agent
Verdict
Input tokens p95 18,400 -> 6,900 (-62%). Cost per task $0.031 -> $0.014. Success 91% -> 91% on 200 cases.
Current composition
| Section | Tokens | Share |
|---|---|---|
| System prompt | 2,100 | 11% |
| Tool definitions (38) | 6,400 | 35% |
| Retrieved docs (12) | 5,800 | 31% |
| History (18 turns) | 3,600 | 20% |
| User message | 80 | 0.4% |
| Output reserve | 420 | 2% |
Proposed budget
| Section | Budget | Rule |
|---|---|---|
| System prompt | 1,400 | cached prefix, duplicates removed |
| Tools | 1,800 | 8 tools in scope per task |
| Retrieval | 2,200 | retrieve 20, rerank, pass 5 |
| History | 1,000 | last 4 turns + summary |
| Output reserve | 500 | unchanged |
Changes
1. Scope tools
35% of every call was 38 schemas the task never used.
Effect: -4,600 tokens/call. Risk: routing changes; verify with 30 routing cases.
2. Rerank retrieval
Twelve chunks, five of which never appear in the answer.
Effect: -3,600 tokens/call. Risk: low; measure gold-present rate.
3. Summarise history beyond four turns
Effect: -2,600 tokens/call. Risk: numbers and deadlines must survive the summary.
4. Cache the system prompt
A timestamp in the prefix was defeating the cache. Cache hit rate 0% -> 78%.
What we did not cut
The four examples that define output format, and the safety rules. They are 900 tokens and carry compliance.
Rollout
Ship behind a flag; compare success and cost for one week.
Connects securely to your tools. The creator never sees your data.
About this skill
Context budget engineering: restructure prompts, tools and retrieval to fit a token budget with the saving measured per request.
Use this skill when:
- hit context limits or token costs
- shrink a prompt without losing quality
- an agent forgets mid-task
- tool output floods the window
Who it's for: Agent developers fighting long context and cost.
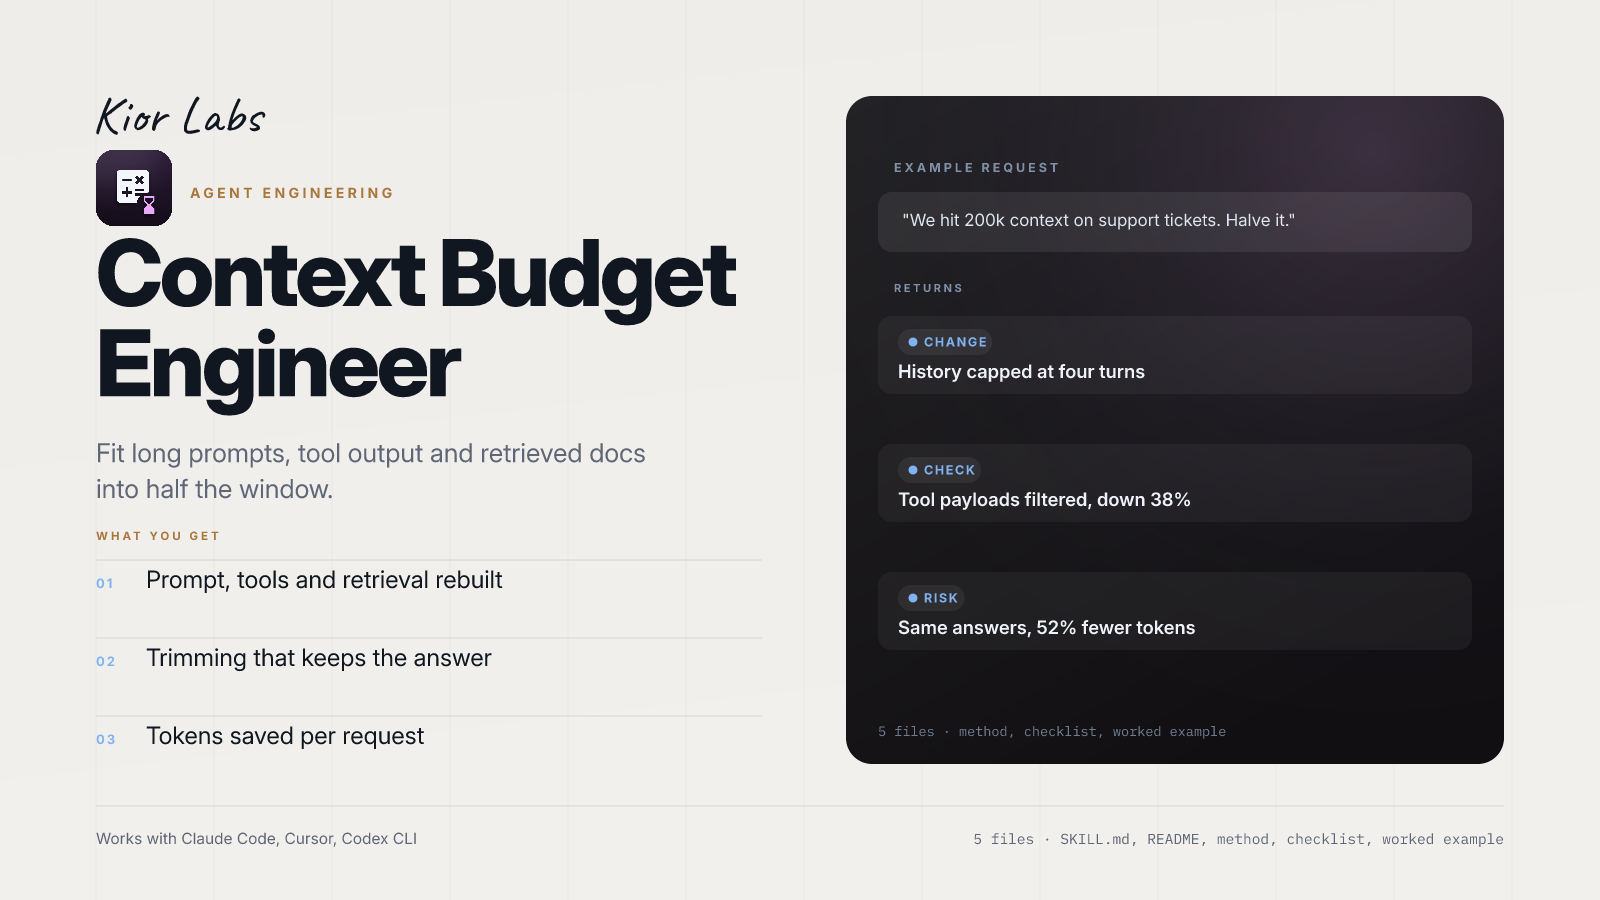
Example request
We hit 200k context on support tickets. Halve it.
What the example returns
- History capped at four turns
- Tool payloads filtered, down 38%
- Same answers, 52% fewer tokens
In the package: five files — SKILL.md with the trigger and workflow, README.md, references/METHOD.md (the full method), references/CHECKLIST.md (the pass/fail gate) and examples/EXAMPLE.md (a worked run you can copy).
Works with Claude Code, Cursor, Codex CLI and any agent that reads SKILL.md. Plain markdown: no API key, no account, no network access.
Find more skills like this on the Claude Skills Marketplace, the Codex Skills Marketplace and the Gemini Skills Marketplace, or browse Claude Skills for Productivity.
Token counts are estimates. Caching strategies may impact privacy. Optimization requires an existing eval set to verify quality isn't lost.
How to use
- 1
Connect your agent to the Agensi MCP
Copy the prompt and paste it into Claude, ChatGPT, Cursor or any agent that supports MCP. It sets up the connection for you. Manual setup
- 2
Sign in to Agensi
Your agent shows a sign-in link. Sign in and click Allow.
- 3
Ask for what you need
Your agent loads this skill and uses it on your task. It always asks before buying a skill.
Reviews
No reviews yet
Be one of the first to try it. Every listed skill goes through the trust checks below.
Security scanned
Checked by our 8-point scan before listing
Fresh listing
Recently published to Agensi
Money-back guarantee
Doesn't do what its page promises? You get your money back.
Trust & safety
Security scan
Security scan passed 2 days ago